When selecting a professional GPU for machine learning, performance, memory capacity, and compatibility are key factors. The NVIDIA Tesla V100 stands out as the best overall choice for its balanced power and scalability. For those prioritizing raw compute, the NVidia RTX PRO 6000 series offers cutting-edge GDDR7 memory and higher throughput, making it ideal for demanding tasks. However, tradeoffs such as cost and power consumption can be significant considerations. Continue reading for a detailed breakdown of each option and what makes them suitable for different needs.

Get privacy and security gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Key Takeaways
- The top picks vary significantly in memory capacity and compute power, influencing their suitability for different workloads.
- Tradeoffs between cost, power consumption, and performance are central when choosing a professional GPU for machine learning.
- Refurbished and renewal options can provide savings but may have tradeoffs in warranty and longevity.
- High-memory GPUs like the NVidia RTX PRO 6000 series excel in large-scale models, whereas more modest options are better for smaller projects.
- Compatibility with existing infrastructure and software ecosystems is critical for seamless deployment and scaling.
| NVIDIA Tesla P100 GPU Computing Processor – 16 GB – Renewed |  | Best Overall for Enterprise AI and Deep Learning | Graphics Coprocessor: NVIDIA Tesla P100 | RAM: 16 GB | Video Output Interface: DisplayPort, HDMI | VIEW ON AMAZON | See Our Full Breakdown |
| HPE NVIDIA Tesla V100 32GB HBM2 PCIe 3.0 x16 Passive GPU Computational Accelerator (Renewed) |  | Best for Scientific Computing and Large-Scale AI | Architecture: NVIDIA Volta GV100 | CUDA Cores: 4,608 | Tensor Cores: 640 | VIEW ON AMAZON | See Our Full Breakdown |
| AI Workload Optimization with GPUs, CUDA, and PyTorch: A Practical Guide to Faster Training, Lower Inference Latency, Better Throughput, and Scalable Deployment |  | Best for Practitioners Seeking Optimization Strategies | VIEW ON AMAZON | See Our Full Breakdown | |||
| Nvidia Tesla P100 16 GB GPU Computing Processor – PCIe 3.0 x16, HBM2, Fanless (Refurbished) |  | Best Fanless Design for Quiet, High-Performance Computing | Graphics Coprocessor: Nvidia Tesla P100 | RAM: 16 GB | GPU Clock Speed: 2400 GHz | VIEW ON AMAZON | See Our Full Breakdown |
| NVlDlA RTX PRO 6000 Blackwell Max-Q Workstation Edition 96GB GDDR7 ECC GPU |  | Best for High-End AI, Rendering, and Virtual Production | Memory: 96GB GDDR7 ECC | CUDA Cores: 24,064 | Ray Tracing Cores: 188 | VIEW ON AMAZON | See Our Full Breakdown |
| NVD RTX PRO 6000 Blackwell Professional Workstation Graphics Card | 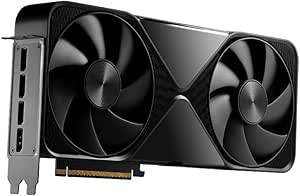 | Best Overall for Heavy-Duty AI and Engineering Workloads | Memory: 96 GB DDR7 ECC | GPU Architecture: Blackwell Streaming Multiprocessor | Ray Tracing Cores: 4th Gen | VIEW ON AMAZON | See Our Full Breakdown |
| NVIDIA L4 |  | Best for High-Performance Visualization and Data Center Integration | Model: 900-2G193-0000-000 | Performance Focus: Graphics and visualization | Application: Data center and professional visualization | VIEW ON AMAZON | See Our Full Breakdown |
More Details on Our Top Picks
NVIDIA Tesla P100 GPU Computing Processor – 16 GB – Renewed
The NVIDIA Tesla P100 stands out as a versatile choice for high-demand enterprise AI workloads, especially when compared to the NVIDIA Tesla V100, which offers more memory and CUDA cores but at a higher cost. Its 16GB of HBM2 memory and support for multiple display outputs make it suitable for server environments that require robust computational power. However, as a renewed product, it may lack the latest features and could have reliability concerns. Its primary limitation is being tailored for enterprise use, so it’s less practical for individual researchers or small teams. This GPU is ideal for data centers and large-scale deployment where raw performance outweighs consumer-friendly features.
Pros:- High-performance GPU suitable for demanding computing tasks
- Large 16GB memory capacity supports sizable datasets
- Supports multiple display outputs for flexible server setups
Cons:- Designed primarily for server and enterprise use, not consumer-grade
- Refurbished condition may affect long-term reliability
- Limited information on cooling and power requirements
Best for: Large organizations and data centers needing reliable, high-performance GPU compute power for demanding enterprise AI tasks
Not ideal for: Small research labs or individual developers seeking consumer-grade hardware with straightforward setup and maintenance
- Graphics Coprocessor:NVIDIA Tesla P100
- RAM:16 GB
- Video Output Interface:DisplayPort, HDMI
- Graphics RAM Type:GDDR6
- Compatible Devices:Server
- Graphics Card Interface:PCI-Express x16
- Display Maximum Resolution:3840 x 1080
Our verdict“This GPU suits large-scale enterprise deployments where maximum computational power and memory are essential, despite some reliability tradeoffs.”
HPE NVIDIA Tesla V100 32GB HBM2 PCIe 3.0 x16 Passive GPU Computational Accelerator (Renewed)
The NVIDIA Tesla V100 offers a leap in performance with 32GB of HBM2 memory and 4,608 CUDA cores, making it a compelling option for intensive scientific computing and AI tasks. Compared to the P100, the V100’s larger memory and Tensor Cores enable faster training of complex models and more accurate scientific simulations. Its support for NVLink allows for scalable multi-GPU configurations, ideal for high-end server environments. However, being a passive cooling model, it demands excellent airflow and a robust chassis, which could be a barrier for smaller setups. As a renewed product, it might lack the warranty coverage of new units. This GPU excels in enterprise and research settings that require maximum performance and reliability for large workloads.
Pros:- Massive 32GB HBM2 memory with ECC for reliability
- High CUDA core count and Tensor Cores accelerate complex workloads
- Supports NVLink for scalable multi-GPU configurations
Cons:- Passive cooling may require enhanced airflow and setup complexity
- Designed for enterprise use, overkill for casual users
- Refurbished status may limit warranty and support
Best for: Research institutions and enterprise AI teams deploying large-scale, multi-GPU systems demanding maximum performance
Not ideal for: Small startups or individual developers without high-end server infrastructure or airflow management
- Architecture:NVIDIA Volta GV100
- CUDA Cores:4,608
- Tensor Cores:640
- Memory:32GB HBM2 ECC
- Memory Bandwidth:900 GB/s
- Interface:PCIe 3.0 x16
- TDP:250W
- NVLink:Yes, 300 GB/s bi-directional
Our verdict“This GPU is best suited for large-scale scientific and AI applications where maximum memory and scalability are critical, despite higher setup demands.”
AI Workload Optimization with GPUs, CUDA, and PyTorch: A Practical Guide to Faster Training, Lower Inference Latency, Better Throughput, and Scalable Deployment
This book provides in-depth strategies for improving AI workloads through GPU, CUDA, and PyTorch optimization techniques. It’s a valuable resource for teams looking to maximize their existing hardware’s efficiency, unlike hardware-centric products like the Tesla P100 or V100. While it doesn’t include physical hardware, its insights are vital for extracting better performance from GPU setups, including those reviewed here. The content may challenge beginners, but it’s perfect for experienced practitioners aiming for scalable deployment and lower inference latency. It’s less relevant for those seeking a plug-and-play solution, but essential for detailed, technical optimization efforts.
Pros:- Comprehensive strategies for GPU and CUDA optimization
- Practical guidance for improving training speed and inference latency
- Focus on scalable deployment techniques
Cons:- No specific hardware or product information
- Technical content may be difficult for newcomers
- Requires prior knowledge of GPU programming
Best for: Data scientists and ML engineers aiming to enhance performance and scalability of GPU workloads
Not ideal for: Beginners or teams looking for straightforward hardware recommendations without deep technical guidance
Our verdict“This guide is well-suited for experienced practitioners seeking to fine-tune AI workloads for maximum efficiency.”
Nvidia Tesla P100 16 GB GPU Computing Processor – PCIe 3.0 x16, HBM2, Fanless (Refurbished)
The Nvidia Tesla P100 in this fanless, refurbished form offers a quiet yet powerful solution for demanding computational tasks, with 16GB of HBM2 memory and a high clock speed of 2400 GHz. Its fanless design reduces noise, making it suitable for environments where silence is valued, such as research labs or open-plan offices. Compared to the active cooling P100, this model relies on chassis airflow, which may limit thermal performance under heavy loads. Its refurbished status ensures cost savings, but potential users should consider the risk of higher operating temperatures and the absence of a cooling fan. It’s an excellent choice for those who prioritize quiet operation over maximum thermal headroom.
Pros:- Fanless, quiet operation ideal for noise-sensitive settings
- High clock speed enhances computational performance
- Refurbished with quality assurance reduces cost
Cons:- Requires compatible high-end hardware for optimal performance
- No active cooling may lead to higher operating temperatures
- Refurbished units may have limited warranty
Best for: Professionals needing high-performance GPU compute with minimal noise in well-ventilated environments
Not ideal for: Heavy workloads or environments with limited airflow, where active cooling is necessary to prevent thermal throttling
- Graphics Coprocessor:Nvidia Tesla P100
- RAM:16 GB
- GPU Clock Speed:2400 GHz
- Graphics RAM Type:HBM2
- Compatible Devices:Desktop
- Interface:PCI-Express x16
- Display Resolution Maximum:7680×4320
Our verdict“This GPU offers a high-performance, quiet solution for professional environments with adequate airflow and cooling capacity.”
NVlDlA RTX PRO 6000 Blackwell Max-Q Workstation Edition 96GB GDDR7 ECC GPU
The NVlDlA RTX PRO 6000 with 96GB of GDDR7 ECC memory is designed for extremely demanding AI, rendering, and virtual production workloads. Its massive memory capacity surpasses the other options here, enabling large models and datasets to reside on-device. Compared to the V100 or P100, this GPU’s advanced ray tracing cores and high bandwidth make it suitable for real-time 3D visualization and high-resolution streaming. Its high power draw of 300W and premium build reflect its enterprise focus, with reliable thermal management and multi-GPU scalability. The OEM packaging suggests it’s geared for professional workstations rather than casual or small-scale setups. It’s best for research, creative professionals, or enterprise environments that demand top-tier GPU resources.
Pros:- Enormous 96GB GDDR7 ECC memory supports large AI models and datasets
- High CUDA core count with advanced ray tracing for real-time graphics
- Reliable thermal management and multi-GPU scalability
Cons:- High power consumption at 300W requires robust cooling
- Premium, OEM-only packaging limits retail availability
- High hardware cost may be prohibitive for some users
Best for: Researchers, digital artists, and enterprise data scientists working on large-scale AI, rendering, or virtual production
Not ideal for: Budget-conscious users or small teams without the infrastructure for high-powered GPUs
- Memory:96GB GDDR7 ECC
- CUDA Cores:24,064
- Ray Tracing Cores:188
- Memory Bandwidth:1792 GB/s
- Power Consumption:300 Watts
- Interface:PCI Express 5.0 x16
- Outputs:4 x DisplayPort 2.1
- Warranty:3 years
Our verdict“This GPU is designed for demanding enterprise and creative workflows where maximum memory and processing power are essential, despite high costs and power needs.”
NVD RTX PRO 6000 Blackwell Professional Workstation Graphics Card
The NVD RTX PRO 6000 Blackwell stands out as the most capable option for demanding AI, simulation, and 3D rendering tasks. Its impressive 96GB DDR7 ECC memory and PCIe Gen 5 support deliver exceptional throughput, making it ideal for large-scale machine learning projects that require substantial data handling. Compared with the NVIDIA L4, which excels in professional visualization but offers less raw compute power, the Blackwell provides a more robust foundation for intensive training workloads. The advanced cooling and high power consumption reflect its focus on sustained performance, but this also means needing a high-quality power supply and a sizable case. This card is best suited for research labs, AI development teams, or engineering firms that demand top-tier performance with stability under heavy loads. Its premium cost and size make it less suitable for smaller or less specialized setups.
Pros:- Massive 96GB DDR7 ECC memory tailored for large AI and simulation projects
- Supports PCIe Gen 5 for faster data transfer, reducing bottlenecks during training
- Advanced cooling system ensures reliable performance during prolonged heavy use
- Multiple high-resolution DisplayPort 2.1 outputs for complex multi-display setups
Cons:- High power consumption at 600W necessitates a robust power supply
- Bulk size and premium price may limit accessibility for smaller operations
Best for: Large AI research teams, data scientists, or engineering firms with demanding workloads and ample infrastructure.
Not ideal for: Small startups or individual developers with limited budgets or space constraints, due to its high cost and power requirements.
- Memory:96 GB DDR7 ECC
- GPU Architecture:Blackwell Streaming Multiprocessor
- Ray Tracing Cores:4th Gen
- Tensor Cores:5th Gen
- Memory Bandwidth:1.8 TB/s
- Display Outputs:DisplayPort 2.1
- Power Consumption:600 watts
- Dimensions:17 x 10 x 5 inches
- Cooling Method:Air
Our verdict“This card makes the most sense for organizations with extensive AI workloads requiring maximum memory and performance capacity.”
NVIDIA L4
The NVIDIA L4 offers a streamlined solution for enterprise visualization and data center applications. While it lacks the extensive specs of the Blackwell, its high-performance graphics capabilities make it suitable for professional visualization workflows and data-centric tasks. Unlike the NVD RTX PRO 6000 Blackwell, which targets AI-intensive workloads, the L4 is optimized for scenarios where rendering speed and efficient data handling in a data center setting are paramount. Its limited detailed specs signal a focus on reliability and integration rather than raw compute power. This GPU is best for organizations needing a versatile, high-performance graphics card for visualization, remote rendering, or enterprise AI deployment without the need for maximum onboard memory or specialized AI cores. Its higher price point and sparse details could be a barrier for smaller teams seeking transparency.
Pros:- High-performance graphics processing suitable for complex visualization tasks
- Designed for integration into data center infrastructures for scalable deployment
- Reliable enterprise-level hardware optimized for continuous operation
Cons:- Limited detailed specifications reduce clarity on performance metrics
- Potentially expensive, especially for organizations with tight budgets
- Less suited for intensive AI training compared to specialized GPUs like the Blackwell
Best for: Enterprises and data centers focused on visualization, remote rendering, or AI deployment in large-scale environments.
Not ideal for: Small-scale machine learning labs or individual developers who need extensive onboard memory or specialized AI features.
- Model:900-2G193-0000-000
- Performance Focus:Graphics and visualization
- Application:Data center and professional visualization
Our verdict“This GPU is ideal for organizations seeking robust visualization and deployment capabilities within data centers, rather than raw AI training power.”
How We Picked
Our evaluation focused on key factors that matter most for machine learning workloads, including raw computational performance, memory size, scalability, and energy efficiency. We also considered build quality, compatibility with popular AI frameworks, and value relative to cost. Products were ranked based on their ability to handle large models, training speed, inference latency, and deployment flexibility. We aimed to highlight options for a range of budgets and performance needs, from entry-level professional GPUs to high-end accelerators suitable for enterprise-scale AI projects.Factors to Consider When Choosing Professional Gpus For Machine Learning
Choosing the right professional GPU for machine learning involves balancing several critical factors. Performance alone isn’t enough; you also need to consider memory capacity, compatibility, and power requirements. Being aware of common pitfalls, such as overestimating your current needs or ignoring future scalability, can save money and frustration. This guide explores the core considerations to help you make a more informed decision, avoiding costly mistakes and ensuring your investment aligns with your project goals.Performance and Compute Power
Evaluate the GPU’s computational capabilities, which directly impact training times and inference throughput. Look for benchmarks in FLOPS and tensor core performance, especially if working with large datasets or complex models. Higher performance GPUs often come with increased costs and power demands, so match the GPU’s power to your workload. Over-investing in raw power for smaller projects can lead to unnecessary expenses, while underpowered options may slow down development and deployment.
Memory Capacity and Bandwidth
Memory size and bandwidth are crucial for training large neural networks or working with high-resolution data. GPUs with 32GB or more are better suited for extensive models, but they also tend to be more expensive. Bandwidth impacts data transfer speeds within the GPU and can influence overall training efficiency. Failing to account for memory needs can result in bottlenecks or the need for multi-GPU setups, complicating your workflow and increasing costs.
Compatibility and Ecosystem Support
Ensure the GPU is compatible with your existing hardware, such as PCIe slots and power supplies. Compatibility with popular AI frameworks like CUDA, PyTorch, and TensorFlow is also vital for smooth integration. Some GPUs are optimized for specific software stacks, which can influence training speed and stability. Choosing a GPU that fits well within your current ecosystem reduces setup time and minimizes compatibility issues down the line.
Power Consumption and Cooling
High-performance GPUs often consume significant power and generate considerable heat. Proper power supplies and cooling systems are necessary to maintain stability and longevity. Overlooking these factors can lead to hardware failures or increased operational costs. Balance the GPU’s power requirements with your infrastructure to avoid bottlenecks, especially if deploying multiple units or in constrained environments.
Cost and Total Ownership
Initial purchase price is just one part of total ownership costs, which include power, cooling, maintenance, and potential upgrades. Consider the long-term value each GPU offers based on your workload and scalability plans. Refurbished or older models can save money but may lack warranty and future-proofing. Investing in higher-end models can be justified for demanding, large-scale projects where time savings and performance gains outweigh the upfront costs.
Frequently Asked Questions
Is it better to buy a new or refurbished professional GPU for machine learning?
Deciding between new and refurbished GPUs depends on your budget and reliability needs. Refurbished options can offer significant savings, but they may come with limited warranties and potentially shorter lifespans. For critical workloads or long-term projects, buying new ensures full warranty coverage and the latest hardware revisions. However, for testing or smaller-scale projects, refurbished GPUs can be a cost-effective choice if purchased from reputable sources.
How much GPU memory do I really need for large-scale machine learning models?
The amount of memory needed depends on your specific model sizes and datasets. For training large neural networks or working with high-resolution data, 32GB or more is advisable. Smaller models or less complex tasks can often be handled efficiently with 16GB or less. Investing in higher memory capacity can prevent bottlenecks during training, but it also increases costs, so balance your needs with your budget.
Can I upgrade my existing workstation with a professional GPU for machine learning?
Upgrading your workstation is often possible if it has compatible PCIe slots and sufficient power supply capacity. Check your hardware specifications carefully to ensure compatibility with your chosen GPU. Upgrades can provide immediate performance improvements, but consider whether your current system’s CPU, RAM, and cooling are adequate for high-end GPUs. Sometimes, a full workstation upgrade may be more cost-effective in the long run if other components are outdated.
What should I prioritize: raw performance or energy efficiency?
This depends on your operational environment and budget. If you need maximum training speed and have ample power and cooling, prioritize raw performance. Conversely, if operational costs or environmental factors are concerns, choosing energy-efficient GPUs can reduce ongoing expenses. Many high-performance GPUs now balance power and efficiency, so consider your workload demands and infrastructure when making this decision.
Are multi-GPU setups worth it for machine learning work?
Multi-GPU setups can significantly accelerate training times for large models, especially when models exceed the memory capacity of a single GPU. However, they introduce complexity in setup, synchronization, and scaling, which can lead to diminishing returns if not managed carefully. For smaller projects or those just starting out, a single high-quality GPU might be more straightforward and cost-effective. For enterprise-scale training, multi-GPU configurations often become necessary to achieve desired throughput.
Conclusion
For those seeking a well-rounded, high-performance option, the NVIDIA Tesla V100 remains the best overall choice thanks to its proven track record and robust ecosystem. Budget-conscious buyers or smaller labs might find the refurbished P100 a compelling alternative, offering solid performance at a lower cost. Professionals working on cutting-edge, large-scale models should consider the NVidia RTX PRO 6000 series for its advanced memory technology and scalability. Beginners or those with modest needs will benefit from entry-level models that balance cost and capability without sacrificing essential features. Ultimately, your choice should align with your workload complexity, infrastructure, and growth plans.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.