
Choosing a Tensor Core GPU for LLM training comes down to memory capacity, sustained performance, power, and system fit. I rank the RTX PRO 6000 Blackwell Workstation Edition first for its 96GB of ECC memory and 5th Gen Tensor Cores, while the DGX Spark is the more compact route to 128GB unified memory. The RTX PRO 6000 Max-Q keeps the same 96GB capacity in a 300W, dual-slot design, trading some power headroom for easier integration. These are distinct systems: a powerful full-size card, a compact integrated desktop, and an efficiency-focused workstation card. The right choice depends on whether your limiting factor is model size, power budget, or flexibility.

Get privacy and security gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
Complete the kit
Key Takeaways
- The RTX PRO 6000 Blackwell Workstation Edition pairs 96GB of ECC memory with 5th Gen Tensor Cores, making it my strongest all-around choice when a system can support its 600W draw.
- The DGX Spark has 128GB of unified memory and a stated capacity for models up to 200 billion parameters at FP4, but it is a compact integrated desktop rather than a conventional PCIe GPU upgrade.
- The RTX PRO 6000 Max-Q offers the same 96GB memory capacity as the full-power workstation card at a 300W cap, which can make it a better fit for constrained power and dual-slot builds.
- Memory capacity alone does not define training speed: bandwidth, software support, workload precision, cooling, and the number of GPUs also shape practical results.
- For buyers who want to upgrade an existing workstation, compare the two RTX PRO cards; for buyers who want an integrated local AI system, compare the DGX Spark.
| NVIDIA RTX PRO 6000 Blackwell Professional Workstation Edition Graphics Card – 96GB GDDR7 ECC, 4th Gen RT / 5th Gen Tensor Cores (OEM Packaging) | 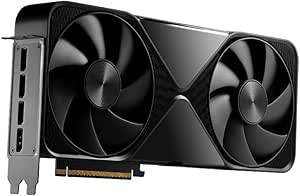 | Best Overall | Architecture: NVIDIA Blackwell | Memory: 96GB GDDR7 ECC | Memory bandwidth: 1.8 TB/s | VIEW ON AMAZON | See Our Full Breakdown |
| NVIDIA DGX Spark Personal AI Desktop Supercomputer with GB10 Grace Blackwell Chip |  | Best Compact Integrated AI Desktop | Chip: GB10 Grace Blackwell | AI performance: Up to 1 petaFLOP | Memory: 128GB unified | VIEW ON AMAZON | See Our Full Breakdown |
| NVIDIA RTX PRO 6000 Blackwell Max-Q Workstation Edition 96GB GDDR7 ECC GPU |  | Best for Power-Constrained Workstations | Architecture: NVIDIA Blackwell Max-Q | Memory: 96GB GDDR7 ECC | Memory bus and bandwidth: 512-bit; 1,792 GB/s | VIEW ON AMAZON | See Our Full Breakdown |
| tensor core gpus for llm training | Memory | Architecture | Interface | Power |
|---|---|---|---|---|
| NVIDIA RTX PRO 6000 Blackwell | 96GB GDDR7 ECC | NVIDIA Blackwell | PCIe Gen 5 | 600W |
| NVIDIA DGX Spark Personal AI D | 128GB unified | — | — | — |
| NVIDIA RTX PRO 6000 Blackwell | 96GB GDDR7 ECC | NVIDIA Blackwell Max-Q | PCI Express 5.0 x16 | 300W maximum |
More Details on Our Top Picks
NVIDIA RTX PRO 6000 Blackwell Professional Workstation Edition Graphics Card – 96GB GDDR7 ECC, 4th Gen RT / 5th Gen Tensor Cores (OEM Packaging)
I put the full-power RTX PRO 6000 Blackwell first for buyers building a serious local training workstation. Its 96GB of GDDR7 ECC memory gives models, optimizer state, and training batches more room on one GPU than smaller-memory cards typically provide, while the listed 1.8 TB/s bandwidth supports frequent movement of data through the accelerator. Its 5th Gen Tensor Cores include FP4 support, a feature aimed at lower-precision AI workloads. The claimed up-to-3X generational AI performance is a vendor figure, so I would not treat it as a direct promise of a particular training-time reduction.
Against the Max-Q version, this card has the more demanding 600W power envelope and a larger physical footprint, but is the more direct choice when a workstation can provide the power, airflow, and space. Compared with DGX Spark, it is a dedicated PCIe GPU with 96GB of discrete memory rather than an integrated system with 128GB unified memory. That distinction matters for compatibility, memory behavior, and whether the buyer already owns a tower. I would favor the Spark for a compact ready-made platform, but this card offers a more conventional workstation upgrade path.
The drawbacks are substantial enough to plan around: 600 watts calls for a robust power supply and careful thermal design, and its 17-inch length rules out many compact cases. OEM bulk packaging also means buyers should confirm what is included and how warranty service works through their seller. For a well-equipped tower running large local fine-tuning workloads, this is the strongest balance in this lineup; for a modest desktop or a low-power build, it is too much card to accommodate casually.
Pros:- 96GB GDDR7 ECC memory provides substantial dedicated capacity for local AI workloads.
- 5th Gen Tensor Cores include FP4 support for compatible lower-precision workflows.
- Listed 1.8 TB/s bandwidth and PCIe Gen 5 suit high-throughput workstation configurations.
- Three-year manufacturer warranty is specified.
Cons:- 600W power consumption requires suitable PSU capacity and cooling.
- 17-inch length and bulk OEM packaging can complicate installation and purchasing.
Best for: Workstation owners training or fine-tuning large models locally who can support a 600W, full-length GPU.
Not ideal for: Compact-PC builders, buyers with limited PSU capacity, or anyone who wants an integrated desktop instead of a component upgrade.
- Architecture:NVIDIA Blackwell
- Memory:96GB GDDR7 ECC
- Memory bandwidth:1.8 TB/s
- Tensor Cores:5th Gen, FP4 support
- Interface:PCIe Gen 5
- Power:600W
- Cooling:Air, double-flow-through design
- Warranty and packaging:Three-year manufacturer warranty; bulk OEM packaging
Our verdict“I recommend this as the most capable conventional workstation choice here when the system can handle its power and size.”
NVIDIA DGX Spark Personal AI Desktop Supercomputer with GB10 Grace Blackwell Chip
The DGX Spark takes a different route from both RTX PRO cards: it is a compact AI desktop built around the GB10 Grace Blackwell chip, not a GPU to slot into an existing workstation. Its 128GB unified memory is the largest stated memory capacity in this comparison, and the product description says it can support models up to 200 billion parameters at FP4. That makes it appealing when the goal is to work with very large models locally in a desk-friendly system, without assembling a tower around a discrete accelerator.
That capacity should not be confused with a guarantee that every model of that size can be trained at a useful speed. Training feasibility depends on precision, sequence length, batch size, optimizer state, and software implementation. The Spark’s up-to-1-petaFLOP AI figure is also not directly comparable to the RTX cards’ specifications without matching workload and precision details. I would choose it over the full-power RTX PRO 6000 when compactness and an integrated NVIDIA software platform are central. I would choose the workstation card instead when PCIe expansion and a dedicated GPU upgrade path matter more.
The main tradeoff is flexibility: this is a complete desktop platform with a specialized use case, not a general-purpose GPU component. The description calls it energy-efficient but does not state a power figure, so buyers comparing energy use should seek system-level details before deciding. Its technical audience and premium positioning make it a poor fit for casual experimentation. For AI developers who want a compact local environment and value its unified memory, it is the distinctive pick; for buyers primarily seeking a powerful add-in card, the RTX PRO models are easier to compare against an existing workstation.
Pros:- 128GB unified memory is the largest stated capacity among these three options.
- Product description states support for models up to 200 billion parameters at FP4.
- Compact desktop format avoids the installation demands of a full-length 600W card.
- NVIDIA AI software stack is integrated for local development and deployment workflows.
Cons:- It is a complete AI desktop, not a replaceable PCIe GPU for an existing tower.
- The description does not state a system power figure or comparable LLM training benchmarks.
- Its specialized platform may exceed the needs of casual users.
Best for: AI developers who want an integrated, compact desktop platform with 128GB unified memory for local model work.
Not ideal for: Buyers upgrading an existing workstation with a PCIe GPU, or those who need clearly specified training throughput and power figures before purchase.
- Chip:GB10 Grace Blackwell
- AI performance:Up to 1 petaFLOP
- Memory:128GB unified
- Stated model capacity:Up to 200 billion parameters at FP4
- Form factor:Compact desktop
- Software:NVIDIA AI software stack
Our verdict“I would choose DGX Spark for compact local AI development and unified memory, while keeping the RTX PRO cards in view for workstation upgrades.”
NVIDIA RTX PRO 6000 Blackwell Max-Q Workstation Edition 96GB GDDR7 ECC GPU
The RTX PRO 6000 Blackwell Max-Q earns its place by retaining 96GB of GDDR7 ECC memory while capping power at 300W. That is half the listed power draw of the full-power RTX PRO 6000, which can make system design, thermal management, and multi-GPU planning more practical. Its dual-slot format also fits standard workstation layouts more readily than the 17-inch full-power card. For LLM work, the attraction is not a smaller memory pool: it is the chance to keep a large model workload on a 96GB GPU with a lower stated power ceiling.
Compared with the full-power card, the Max-Q is the more sensible option when a workstation’s PSU, cooling, or chassis cannot support a 600W accelerator. The listed 1,792 GB/s bandwidth is close to the other card’s stated 1.8 TB/s, but those figures alone do not establish equal training speed; clock behavior, sustained power, and workload all matter. It also lists up to 3,511 TOPS of AI performance, but the description does not provide precision and benchmark conditions that would make this directly comparable to DGX Spark’s petaFLOP claim.
There are real compromises. This is still a professional-grade, 96GB card, so its capabilities may be unnecessary for smaller fine-tuning jobs, and its OEM packaging calls for checking seller and warranty details. It has four DisplayPort 2.1 outputs, useful in display-heavy workstation setups but secondary to most training decisions. I would rank it behind the full-power card for buyers with ample power and cooling, but ahead of it for a dual-slot workstation where the 300W limit is decisive. Buyers wanting more memory in a compact integrated system should compare DGX Spark instead.
Pros:- 96GB GDDR7 ECC memory matches the full-power RTX PRO card’s stated capacity.
- 300W maximum power is substantially below the full-power card’s 600W draw.
- Dual-slot form factor can fit workstation layouts that cannot take a long, high-power card.
- PCIe 5.0 x16 and four DisplayPort 2.1 outputs provide modern workstation connectivity.
Cons:- OEM bulk packaging means no retail box and warrants checking seller support details.
- Professional-grade capacity may be unnecessary for smaller local fine-tuning workloads.
- Listed AI TOPS figure lacks conditions for direct comparison with the other products’ claims.
Best for: Workstation builders who need 96GB of dedicated ECC GPU memory but have a 300W power ceiling or a dual-slot chassis constraint.
Not ideal for: Buyers seeking an integrated desktop, or those whose workloads do not benefit from a professional 96GB accelerator.
- Architecture:NVIDIA Blackwell Max-Q
- Memory:96GB GDDR7 ECC
- Memory bus and bandwidth:512-bit; 1,792 GB/s
- AI performance:Up to 3,511 TOPS
- Power:300W maximum
- Form factor:Dual-slot
- Interface:PCI Express 5.0 x16
- Warranty and packaging:Three-year manufacturer warranty; OEM/bulk packaging
Our verdict“I recommend the Max-Q when 96GB of dedicated GPU memory matters but a 600W card does not fit the workstation’s power or cooling limits.”

How We Picked
I ranked these products by how directly their stated specifications address local LLM training: memory capacity, Tensor Core generation or stated AI capability, bandwidth, power envelope, and the kind of computer each option requires. The 96GB cards stand out for dedicated GPU memory and workstation integration, while the DGX Spark’s 128GB unified memory supports a different compact-system approach. I treat stated model-size and performance figures as vendor specifications, not as guarantees of training speed across every model or software stack.
I also weighed practical constraints that can decide a purchase before benchmark comparisons matter. A 600W card calls for substantial power and cooling capacity; the Max-Q’s 300W limit and dual-slot form factor are easier to accommodate in some workstations. DGX Spark avoids choosing and installing a separate GPU, but it is a complete desktop platform rather than a component for an existing tower. Because the descriptions do not provide comparable training benchmarks, I do not claim a universal speed winner. My order reflects the balance of memory, stated AI hardware, and flexibility for the specific LLM-training use case.
| tensor core gpus for llm training | Architecture | Interface | Warranty and packaging | AI performance |
|---|---|---|---|---|
| NVIDIA RTX PRO 6000 Blackwell | NVIDIA Blackwell | PCIe Gen 5 | Three-year manufacturer warranty; bulk OEM packaging | — |
| NVIDIA DGX Spark Personal AI D | — | — | — | Up to 1 petaFLOP |
| NVIDIA RTX PRO 6000 Blackwell | NVIDIA Blackwell Max-Q | PCI Express 5.0 x16 | Three-year manufacturer warranty; OEM/bulk packaging | Up to 3,511 TOPS |
Factors to Consider When Choosing Tensor Core Gpus For Llm Training
I would start with the kind of system you want to own, then check the workload’s memory needs. A 96GB card and a 128GB unified-memory desktop are not interchangeable merely because both can hold large models. Training also needs room for more than model weights, so the usable model size depends on the training method and configuration.
Estimate memory for the training method
Model weights are only part of the memory budget. Full fine-tuning often needs space for gradients, optimizer states, activations, and temporary buffers as well. Parameter-efficient methods such as LoRA can reduce that burden, though sequence length and batch size still affect memory use. The product descriptions give memory capacities and, for DGX Spark, a stated maximum model size at FP4; they do not specify a universal training configuration for that capacity. I would match capacity to the exact model, precision, and fine-tuning method before treating a headline parameter count as a fit guarantee.
Compare power and system fit
The full-power RTX PRO 6000 draws up to 600W and measures 17 inches long, so PSU capacity, connector support, case clearance, and airflow are purchase requirements. The Max-Q’s 300W cap and dual-slot format suit more constrained workstation builds, but buyers should still verify cooling and motherboard clearance. DGX Spark is described as a compact desktop, avoiding discrete-card installation; its listed information does not include a system power figure. I would check the full system configuration rather than infer consumption from its energy-efficient description.
Treat AI performance claims carefully
These products list unlike figures: the full-power card cites up to 3X previous-generation AI performance, the Max-Q lists up to 3,511 TOPS, and DGX Spark cites up to 1 petaFLOP. Without common precision, benchmark, and workload conditions, those numbers do not form a reliable ranking of LLM training speed. Memory bandwidth, software kernels, sustained power, and model setup can all change real results. If throughput determines your purchase, look for independent benchmarks using the models and training method you plan to run.
Choose a component or a complete desktop
The two RTX PRO options are PCIe workstation GPUs, suited to buyers who already have or are building a compatible tower. They also leave room to choose the CPU, storage, memory, and other accelerators separately. DGX Spark is the integrated choice for someone who wants an NVIDIA AI development platform in a compact desktop. I would favor it when convenience and unified memory matter more than component-level flexibility; I would favor an RTX PRO card when I need a dedicated GPU in a larger workstation.
Check software, precision, and support
Tensor Core capability only helps when the training framework, libraries, and model code support the relevant operations. FP4 can reduce memory use and accelerate supported AI workloads, but it is not appropriate for every training setup or quality target. Confirm that your framework and preferred fine-tuning tools support the chosen platform and precision. Both RTX PRO descriptions list a three-year manufacturer warranty, while the DGX Spark description here does not specify one. The cards ship in OEM or bulk packaging, so I would verify included accessories, seller support, and warranty handling before ordering.
Frequently Asked Questions
Which of these is the best Tensor Core GPU for LLM training?
I rank the full-power RTX PRO 6000 Blackwell first for a compatible workstation because it combines 96GB of ECC memory, 1.8 TB/s bandwidth, and 5th Gen Tensor Cores with FP4 support. That recommendation assumes the system can handle its 600W draw and large footprint. The Max-Q is a better match if power is constrained, while DGX Spark suits buyers who want a compact integrated AI desktop with 128GB unified memory.
Does DGX Spark support training a 200-billion-parameter model?
The product description states that DGX Spark supports models up to 200 billion parameters at FP4. That is a stated model-capacity claim, not a guarantee that every 200-billion-parameter model can be trained with every method or at a practical speed. Fine-tuning approach, sequence length, batch size, and software support all affect what fits and how it performs, so I would confirm the intended workload before buying.
Should I choose the RTX PRO 6000 or the Max-Q version?
I would choose the full-power RTX PRO 6000 if the workstation has the PSU capacity, cooling, and space for a 600W, 17-inch card and I want the full-power model. The Max-Q preserves 96GB of ECC memory with a 300W limit and dual-slot form factor, which is a more practical fit for some towers. Their memory specifications are close, but that alone does not prove identical training throughput.
Is more GPU memory always better for LLM training?
More memory can let a larger model or more of its training state remain on the accelerator, reducing the need to lower batch size or use offloading. It does not automatically make training faster: compute throughput, bandwidth, precision, framework support, and cooling matter too. I would size memory for the chosen model and training method, then compare performance evidence for that workload rather than choosing by capacity alone.
Can I compare the listed TOPS and petaFLOP figures directly?
I would not compare the Max-Q’s 3,511 TOPS claim directly with DGX Spark’s up-to-1-petaFLOP figure or the full-power card’s up-to-3X generational claim. The descriptions do not establish common precision modes, benchmark methods, or LLM training workloads for those figures. For a speed decision, use comparable benchmarks from the models and training setup you expect to run.
Conclusion
For a high-capacity workstation build, I recommend the RTX PRO 6000 Blackwell if 600W power delivery and its physical size are manageable. If your tower needs the same 96GB memory class with a lower power ceiling, the Max-Q is the more practical workstation pick. For AI developers who prefer a compact integrated desktop and value 128GB unified memory, I would choose DGX Spark, while checking how its platform fits the intended training workflow. The best choice is the one whose memory, power envelope, and system format match the model you plan to train.
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.